How to Become a Data Engineer Mid-Career: A Data Engineer Career Path for Working Professionals
TL;DR
We help experienced IT, software, BI, testing, database, and operations professionals move into data engineering without discarding earned credibility. This guide shows how we select a target role, turn prior work into evidence, close focused gaps, build one production-minded project, reframe experience truthfully, and apply before every gap closes.
How to Become a Data Engineer Mid-Career: A Practical Career Path for Working Professionals
The market does not need another beginner checklist. For someone pursuing a data engineer mid-career transition, the stronger approach is to show how existing experience connects to real engineering responsibilities and where new technical proof is needed.
A practical data engineering career path should build on your existing seniority rather than make you start from zero. That means choosing one realistic target role, mapping your current experience to its requirements, closing the most important skill gaps, building one defensible end-to-end project, and presenting your previous work accurately.
This guide explains how to make a data engineer mid-career transition without pretending to be a beginner or claiming experience you do not have. You will get a practical role-selection method, transferable-skills matrix, project framework, and application-readiness checklist.
How to Choose a Data Engineering Career Path as a Working Professional
The first step in a data engineer mid-career transition is choosing a realistic destination before deciding what to learn. Your existing background can help narrow the options instead of forcing you to study every area of data engineering at once.
A software developer may be well positioned for pipeline-focused engineering roles because of existing programming and deployment experience. A BI professional may have a stronger starting point in analytics engineering, while someone from database or operations work may already understand ETL, performance, monitoring, and data infrastructure.
An ed-tech training provider can help structure this transition, but the starting point should still be the roles you want to target. Review around 15 relevant job descriptions and record the job title, seniority, industry, technical requirements, responsibilities, and recurring business problems. This gives you a clearer picture of what employers actually expect rather than what a generic course outline says you should learn.
Treat a requirement as recurring when it appears in at least eight of those 15 roles. This gives you a more practical learning plan because your study priorities come from the roles you actually want to pursue.
For a data engineer mid-career candidate, this exercise also prevents the common mistake of learning every cloud platform and data tool simultaneously. Choose one platform family based on your job sample, then focus on understanding the underlying engineering concepts well enough to explain your decisions.
What Experience Transfers into Data Engineering?
A data engineer mid-career transition becomes easier when you separate transferable experience from technical proof that still needs to be developed. Employers may value your previous engineering, operations, analytics, or domain experience, but they still need evidence that you can handle data engineering responsibilities.
Previous Background | Credible Evidence Already Present | Technical Proof To Add |
Software Engineering | APIs, code review, deployment, error handling, version control | Data models, batch design, distributed processing decisions |
Testing/QA | Test design, defect triage, release quality, regression prevention | Data-quality tests, freshness checks, pipeline observability |
BI/Analytics | SQL, metric definitions, reporting dependencies, stakeholder context | Reusable transformations, orchestration, modeled datasets |
Database/DBA | Schemas, query tuning, access control, performance, backup practices | Cloud storage, processing patterns, pipeline automation |
IT Operations | Monitoring, incident response, automation, access management | Ingestion design, data contracts, transformation evidence |
Domain Operations | Workflow knowledge, source-system context, governance awareness | SQL/Python proof and documented technical project |
Microsoft's current data engineering study material places significant emphasis on data processing, alongside storage, security, monitoring, and optimization. For a data engineer mid-career learner, that balance is useful because it shows why studying only SQL or cloud services is not enough. This is also where Microsoft Fabric Training can be useful, as it exposes learners to a broader data environment rather than treating individual tools and skills in isolation.
Build A Practical Skill Gap Matrix
Create a simple scorecard for the capabilities that appear repeatedly in your target roles. Score yourself from 0 to 3 based on actual evidence rather than how familiar a topic feels.
Capability | Evidence To Build | Ready-Enough Standard |
SQL | Multi-source joins, window functions, incremental transformations | Explain table grain, joins, and data checks |
Python | Reusable ingestion and transformation code with tests | Debug and document a pipeline component |
Cloud | Storage, identity, access, and cost-aware choices | Explain why each managed service exists |
Orchestration | Dependencies, schedules, retries, alerts, run evidence | Describe failure recovery |
Spark | Transformations, partitioning rationale, output design | Explain when distributed processing is justified |
Data Modeling | Fact/dimension design, lineage, business definitions | Defend a model against stakeholder needs |
If you already work heavily with databases, spend additional time understanding modern cloud storage and lakehouse patterns. The objective of a data engineer mid-career plan is not to master every technology immediately, but to become credible against the requirements of your selected roles.
What One Project Proves Production-Oriented Judgment?
For a data engineer mid-career candidate, one complete and well-explained project can be more useful than several disconnected notebooks. A strong project should demonstrate how you approach ingestion, validation, transformation, orchestration, reliability, and business requirements together.
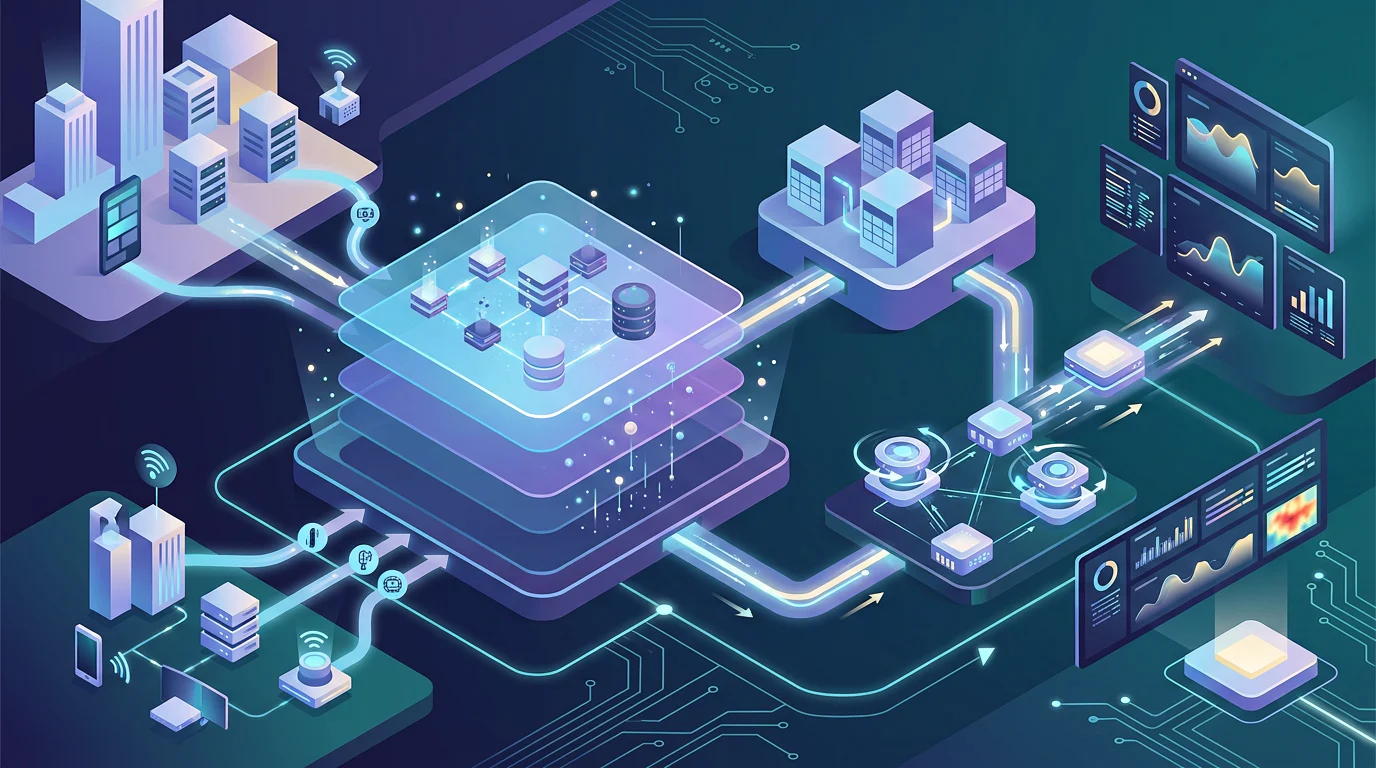
One practical option is to build a pipeline that ingests a daily public API alongside two batch files. Validate schemas and data freshness, transform raw records into documented business entities, publish an analytics-ready table, and expose enough run information to demonstrate that the pipeline can be monitored.
Start by defining the source and its data contract. Document the available fields, expected arrival frequency, handling of late or malformed records, data definitions, and any sensitive-field considerations. Then design the workflow around realistic failures. Include dependencies, retries, logging, and recovery steps so you can explain what happens when a source is unavailable or a transformation fails.
Tools such as Airflow model workflows through tasks and dependencies, making orchestration decisions easier to demonstrate. Your project should show not only that the pipeline runs successfully, but also that you have considered what happens when it does not.
Add checks for duplicate records, invalid schemas, unexpected nulls, freshness issues, and rerun safety. These details help demonstrate the production mindset expected from someone making a data engineer mid-career transition. Your processing and modeling choices should also have a reason behind them. Define the business question, identify the grain of each important table, and explain why you selected a particular processing approach rather than adding technology simply to make the project look advanced.
Finally, package the project as evidence. A strong Data Engineering Program should help you build work that can actually demonstrate these skills, so include a README, architecture diagram, source and transformation code, tests, run logs, a short decision record, and a walkthrough that explains what you built and why.
How to Reframe Experience and Apply Before Every Gap Closes
A data engineer mid-career application should not hide your previous work or rewrite your job history to sound more technical. Instead, identify the engineering signals already present in your experience and connect them to the requirements of your target role.
Look for evidence around data volume, reliability, automation, stakeholder requirements, quality controls, delivery constraints, and measurable outcomes. Keep your actual title and responsibilities unchanged, and never add tools or ownership you did not have.
A useful structure is simple: describe the action, explain the system or data context, show the reliability or business impact, and include a verified result. This creates a stronger description without exaggerating your experience.
You do not need to close every skill gap before applying. For a data engineer mid-career candidate, being able to explain your target stack, technical foundations, completed project, and plan for unresolved areas can be more valuable than waiting indefinitely.
Your resume, portfolio, and interview narrative should tell the same story. The resume should establish your transferable experience, the project should demonstrate your newer technical capabilities, and the interview should connect the two.
Use A 90-Day Transition Plan
Days 1–30: Select one target role and analyze 15 job descriptions. Identify recurring requirements, choose your platform family, and assess your current skills against the most important capabilities.
Days 31–60: Strengthen SQL, Python, cloud, orchestration, and modeling fundamentals based on your gap analysis. Begin building your end-to-end project and document your technical decisions as you go.
Days 61–90: Complete the project, package the evidence, update your resume and portfolio, and begin applying to roles where your existing experience and new technical proof overlap.
This approach keeps a data engineer mid-career transition focused on evidence rather than endless preparation. You are not trying to become an expert in every data technology before your first application.
Build Your Next Data Engineering Proof with Vision Board
A successful data engineer mid-career transition requires more than completing another course or collecting certifications. You need a clear target role, relevant technical evidence, and a credible way to explain how your previous experience supports the move.
Vision Board helps working professionals turn existing career experience into stronger data and AI evidence. The approach accounts for real delivery responsibilities, stakeholder trade-offs, systems experience, quality requirements, and operational constraints.
You can use this process to identify a realistic target role, interpret job requirements, select the right technical stack, shape a practical project, and translate previous achievements into evidence without overstating them.
The most effective starting point is to define the job you want and the proof you need before choosing between self-study, guided learning, or a project-centered approach. That keeps your learning connected to an actual career outcome rather than becoming another open-ended study plan.
Explore all our courses today!
FAQs on data engineer career path for working professionals
Can I Switch to Data Engineering from IT?
Yes, IT professionals can make a data engineer mid-career transition by building on experience in monitoring, automation, systems, access management, and incident response. Add SQL, Python, data modeling, ingestion, and pipeline evidence through one complete project.
Do I Need to Learn Every Data Platform Before Applying?
No. A focused data engineer mid-career plan should prioritize the platform family that appears most often in your target roles while developing transferable fundamentals in SQL, Python, modeling, and orchestration.
What Project Should a Mid-Career Candidate Build?
Build a documented batch pipeline with source contracts, transformations, data-quality checks, orchestration, failure recovery, and an analytics-ready output. A project like this gives a data engineer mid-career candidate evidence across several core engineering responsibilities.
How Should I Reframe My Previous Experience?
Keep your actual title and responsibilities, then emphasize verified experience with automation, quality, reliability, scale, systems, and stakeholder impact. A strong data engineer mid-career application should connect those existing signals to the technical evidence you have recently built.