
SQL and ETL Skills for Azure Data Engineer Training
Role-specific Azure data engineering training for IT professionals moving from SQL, ETL, database, QA and support work.
By Devikrishna R, Founder · Reviewed 20 Sept 2026
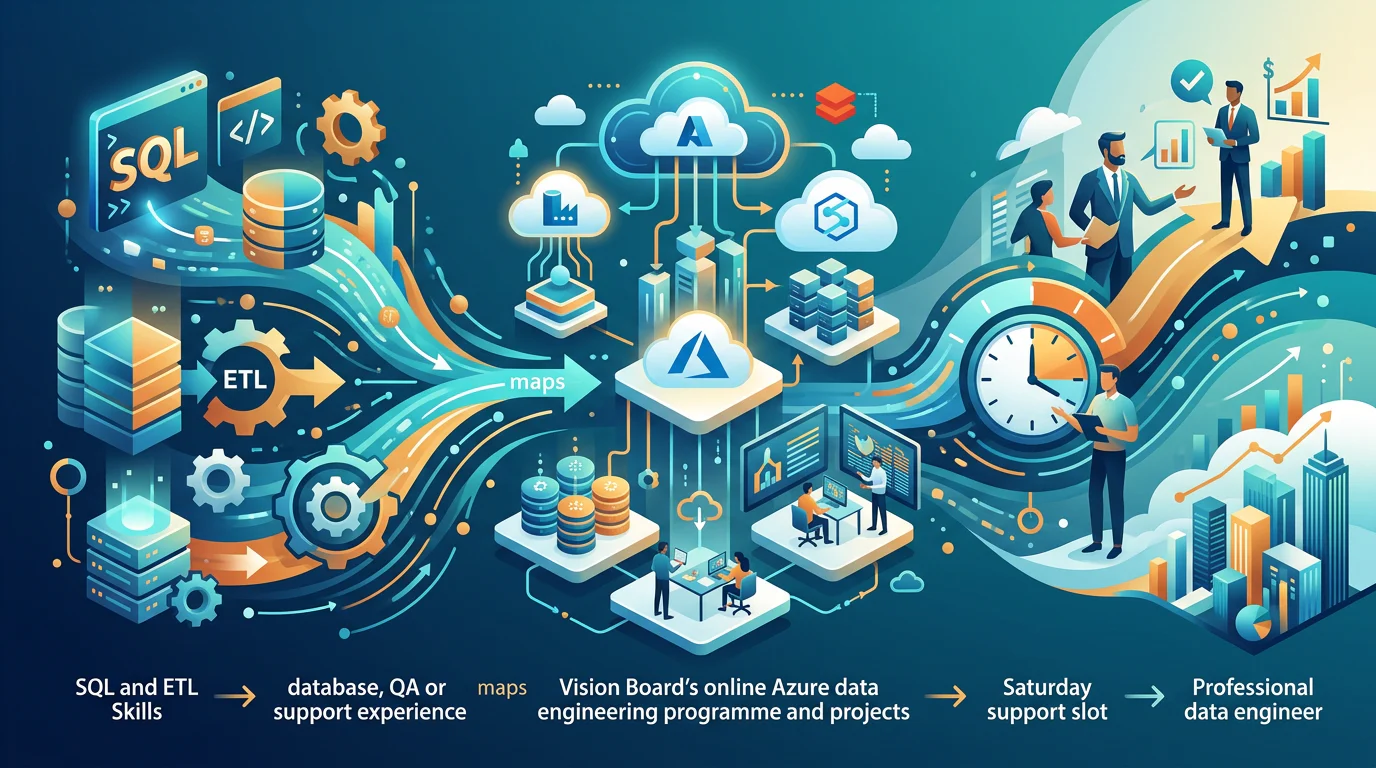
In brief
Microsoft's current data-engineering credential expects skills in data loading, orchestration and SQL, so SQL and ETL experience can be a practical starting point. Vision Board's online Azure Data Engineering + GenAI programme adds Azure tools, projects and interview preparation for IT professionals.
What the programme covers
SQL, Python and PySpark
Build from relational-query work into data-engineering transformations.
- Advanced SQL is listed in the curriculum
- Python for data science and engineering
- PySpark transformations, joins and DataFrames
- Spark performance and fault-tolerance topics
Azure Data Factory pipelines
Practise data movement, transformation and pipeline operations.
- Data pipelines and data flows
- SQL Server, REST API, CSV, JSON and Parquet sources
- Incremental and batch pipelines
- Triggers, parameterisation, monitoring and debugging
Azure data-platform tools
Work through the services named in the published curriculum.
- Azure Databricks and Delta Lake
- Azure Data Lake Storage
- Azure Synapse Analytics
- Azure Event Hubs and Stream Analytics
- Microsoft Fabric lakehouse and data warehousing
Batch 12 programme
An online programme with teaching, practice and career-preparation components.
- ₹33,898.31 displayed price, 2026
- Four-month advertised duration
- Live classes, recorded videos, assessments and interactive sessions
- Saturday doubt clearing, 10am to 12pm
- Three listed projects, including Azure Fabric and GenAI
- Mock interviews, résumé and LinkedIn preparation
Where we work
- SQL professionals
- ETL professionals
- Database administrators
- QA professionals
- IT support professionals
Start from the work you already know
Microsoft’s current Fabric Data Engineer Associate criteria centre on data loading patterns, data architectures, orchestration, data transformation, solution management and optimisation. Microsoft also names SQL, PySpark and KQL as relevant data-manipulation skills. That makes existing SQL and ETL work a useful starting point for this training, not a substitute for the Azure, Spark and project work ahead.
- SQL and ETL professionals: connect query, transformation and workflow experience to Azure Data Factory, PySpark and data-pipeline practice.
- Database administrators: build from relational and warehouse knowledge. Microsoft’s Databricks guidance says SQL is a good starting language for database and data-warehousing backgrounds.
- QA and support professionals: use the curriculum to identify which tools, data workflows and project expectations are new before committing to the programme.
The programme builds around pipelines, data platforms and interview work
Vision Board’s published Batch 12 programme listing includes advanced SQL, Python, PySpark, Azure Data Factory, Azure Databricks, Azure Data Lake Storage, Azure Synapse Analytics, Azure Event Hubs, Azure Stream Analytics, Microsoft Fabric, Generative AI and interview preparation. The listed project areas are end-to-end implementation, Azure Fabric and GenAI.
Azure Data Factory is relevant because it orchestrates and automates data movement and transformation through cloud data workflows, as Microsoft’s Azure Data Factory documentation explains. The training is therefore better suited to professionals prepared to practise pipeline and transformation work than to people seeking a certificate without assessments or project work.
Keep the credential target current
Microsoft retired Exam DP-203 on 31 March 2025, according to its DP-203 study guide. The current Microsoft data-engineering credential is Fabric Data Engineer Associate, associated with Exam DP-700. Treat DP-203 as historical course context, not as a current certification outcome.
Related decisions
Compare the Azure Data Factory and Microsoft Fabric learning paths before choosing a tool sequence. Then use the Azure Data Engineering project path to decide what your portfolio should demonstrate.
Keep reading
Frequently asked
SQL and ETL experience maps to important current data-engineering work, including data transformation, loading patterns and orchestration. Microsoft’s current Fabric Data Engineer Associate guidance also identifies SQL as a relevant skill, while the programme adds Azure Data Factory, Databricks, PySpark and project work.
Database administrators can use relational and data-warehouse knowledge as a starting point for Azure data engineering. Microsoft’s Databricks guidance identifies SQL as a good language for database and data-warehousing backgrounds, while the programme introduces cloud data tools and pipeline-focused implementation.
Vision Board’s Batch 12 programme FAQ lists doubt-clearing sessions every Saturday from 10am to 12pm. The programme also lists live classes, recorded videos, assessments and interactive sessions, so professionals can consider the fixed support window alongside their existing work schedule.
The programme curriculum lists DP-203, DP-600 and DP-700 preparation topics, but DP-203 is not a current Microsoft certification target. Microsoft retired DP-203 on 31 March 2025, and its current Fabric Data Engineer Associate credential is associated with Exam DP-700.
Vision Board lists three project areas in the programme: an end-to-end implementation, an Azure Fabric project and a GenAI project. These project areas sit alongside Azure Data Factory, Databricks, SQL, PySpark and interview-preparation topics in the published curriculum.
Discuss Your Azure Data Engineering Starting Point
Bring your current role, tools and weekly availability to a role-fit conversation.
Discuss My Role Fit