An Azure Data Engineer Portfolio Playbook Reviewers Can Inspect
A practical sequence for choosing three builds, creating reviewer-ready evidence and explaining the work in an interview.
4 chapters · Updated Sep 30, 2026 · By Devikrishna R
- 3
- current Microsoft data-engineering role areas: ingest and transform, manage, monitor and optimise
- 31 March 2025
- retirement date for Microsoft Certified: Azure Data Engineer Associate
In brief
Build three Azure projects in sequence: a batch pipeline, an incremental pipeline, and a monitored lakehouse workflow. Each project should leave inspectable proof of how data moves, how correctness is protected, and how the workflow runs.
Choose a data problem before choosing Azure services
Start with a data source that has a defined owner, a usable schema and a question that can be answered from the output. New York City TLC trip records are one workable example because the records include pickup and drop-off dates, locations, distance, fares, payment types and passenger counts, while the agency also warns that it does not guarantee the data’s accuracy. That makes the dataset useful for demonstrating both pipeline design and validation decisions. NYC TLC’s trip-record documentation explains those fields and limitations.
Write a one-paragraph project brief before opening Azure. Name the consumer, the question, the source, the refresh expectation and the output table or dashboard-ready dataset. Then draw the source-to-output path. A project that begins with a business question gives you a reason for every transformation and a way to explain why a field was retained, cleaned or rejected.
Create the repository at the start, not at the end. GitHub describes a README as the place to explain a project and document installation or use. Put setup, run instructions, expected outputs and known limits there as you build.
Takeaway: A clear data question and a readable README turn a technical exercise into a project another person can inspect.
Build correctness in before adding scale
Make the first build a batch copy pipeline. Use Azure Data Factory to move a defined source into a storage or database target, then prove that the destination contains the expected output. The point is not to collect services. The point is to show that you can define a source, configure a destination, run a pipeline and verify the result.
Make the second build incremental. Microsoft’s Azure Data Factory guidance documents watermark-based loading as a workflow that retrieves an old watermark and a new watermark, copies rows between those values, then stores the new watermark for the next run. Microsoft’s incremental-load documentation also covers change tracking, LastModifiedDate and time-partitioned paths. Pick one method and state why it fits the source.
Your evidence should demonstrate a change, not merely show a successful screen. Add data or modify a source record, run the pipeline again, and retain the old and new run details. Record the expected row count, the actual row count, the watermark value and the handling for duplicates or late records. This is where an interviewer can ask what would happen after a failed run, and where your design should have an answer.
Takeaway: An incremental project proves that your pipeline can preserve state and explain what changed between runs.
Move from a run to production-like proof
Use the third project to organise data as a lakehouse workflow. Azure Databricks defines the medallion pattern as bronze for raw ingestion, silver for cleaning and validation, and gold for dimensional modelling and aggregation. Microsoft’s medallion guidance gives the technical basis for this structure. Keep the architecture diagram simple enough that a reviewer can follow the route from raw source to business-ready table.
Then add operating evidence. Azure Data Factory can monitor pipeline runs in Data Factory Studio, and Azure Monitor can surface availability, performance, resilience, alerts and logs. Microsoft’s monitoring documentation supports using run history and logs as evidence rather than relying on a final output alone. Add a scheduled workflow, retain one successful run and one investigated failure or quality exception if you can reproduce it safely.
Finally, include version-control and deployment material. Azure Data Factory’s CI/CD guidance describes promoting pipelines between development, test and production with Azure Pipelines or Resource Manager templates. Microsoft’s CI/CD documentation is a useful implementation reference.
What each portfolio level must show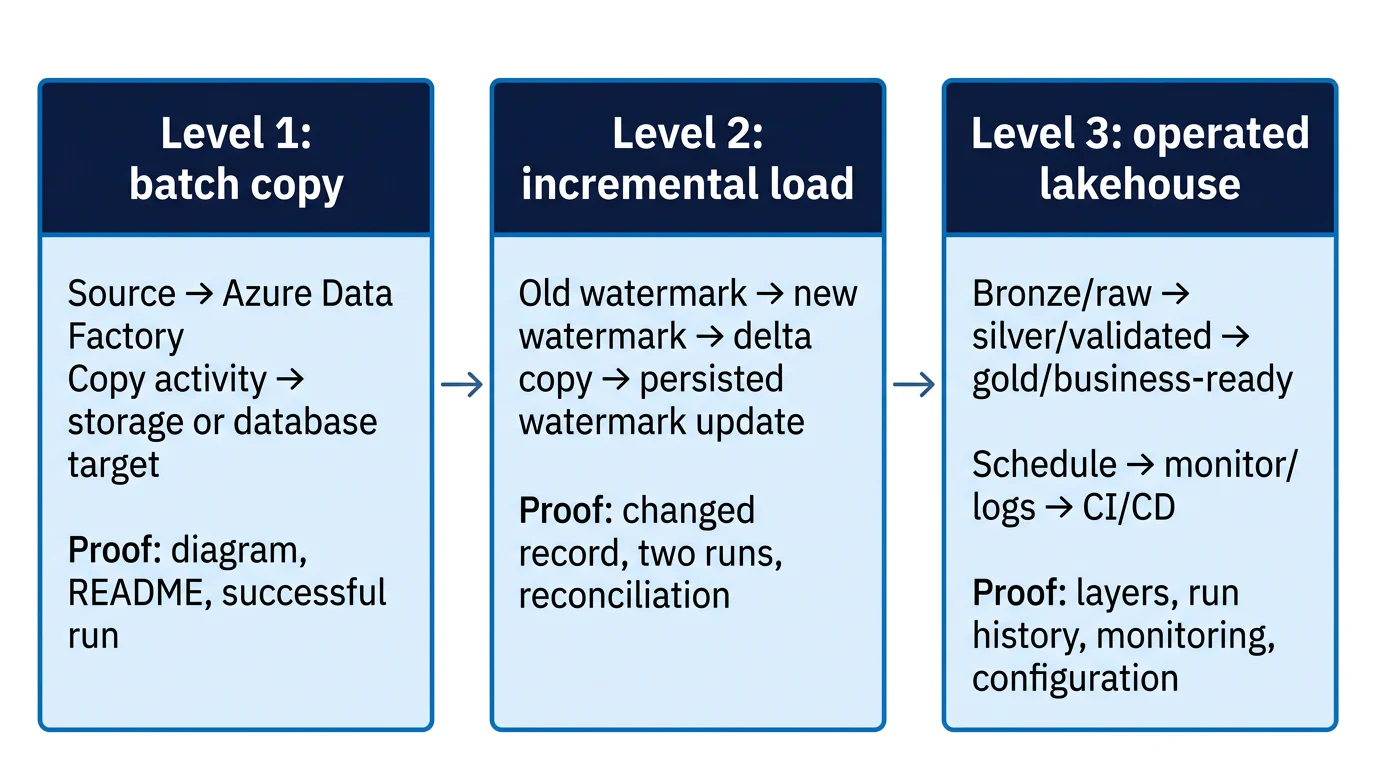
Takeaway: A monitored, deployable workflow shows operational judgement that a one-off notebook cannot show.
Prepare one interview story for every project
Use the same six prompts for each project: What problem did you solve? What was the source? How did data move? How did you protect correctness? What evidence proves the run? What would you change with more volume, more users or stricter reliability requirements? Answer each prompt in short notes before you practise aloud.
Your explanation should distinguish facts from choices. “The source publishes these fields” is a fact. “I used a watermark because I needed only new or changed rows” is a design choice. “I would add a dead-letter path for malformed records” is an improvement. That structure gives an interviewer room to assess your reasoning without forcing you to claim a production outcome you did not measure.
Microsoft’s current Fabric Data Engineer Associate material groups the role around ingesting and transforming data, securing and managing an analytics solution, and monitoring and optimising it. Microsoft’s DP-700 role description makes a useful coverage check for your stories. Practise the explanation with six Azure data-engineering scenario drills, then update the README when a question exposes an unclear decision.
Takeaway: A project becomes interview-ready when you can explain its evidence, trade-offs and next improvement without reading from the code.